An FDF annotation importer can return the number of entries it parsed while adding none of them to the document: every entry counted, every entry dropped. TPDFlib.ImportAnnotationsFromFDFString in losLab PDF Library reads keys in any order, parses /Rect correctly and locale-independently, and returns the number of annotations actually added, while the matching exporter writes the annotation's real /Rect, so an export, import and second export produce byte-identical FDF. The rest of this note explains how one wrong starting offset produces a perfect silent failure, which three other traps hide behind it, and how to check an import yourself instead of trusting a return value
The scenario is ordinary. A reviewer marks up a contract, the comments travel as an FDF file (Acrobat calls it Export Comments), and your Delphi service merges them into a clean copy with an FDF import call. The call returns 7, the log says "7 comments imported", the job goes green, and the output PDF has no comments at all. Nothing raised, nothing warned, and the number looked plausible because it was the true count of entries in the file. That is the worst shape a bug can take: a function whose only signal of success is a counter that is computed independently of the work it claims to report
Why can an FDF import report success but add nothing?
Because a name reader can start in the wrong place, and a counter can live outside the code that does the work. A key finder that returns the position immediately after /Subtype lands on the whitespace before the value. A ReadName that starts at that space and stops at the first whitespace character stops before reading anything, so every subtype comes back empty. A helper such as AddAnnotationToPage that refuses to build an annotation without a subtype is making the correct defensive choice in isolation, but if it is a procedure with no return value and the caller's Inc(Result) sits outside it, the two guards together convert "nothing worked" into "everything worked". The correct name reader skips whitespace, requires the leading / of a PDF name object, and stops at any delimiter, including [, ( and ), so /Subtype/Text and /Subtype /Text both yield Text; that is how losLab PDF Library reads names
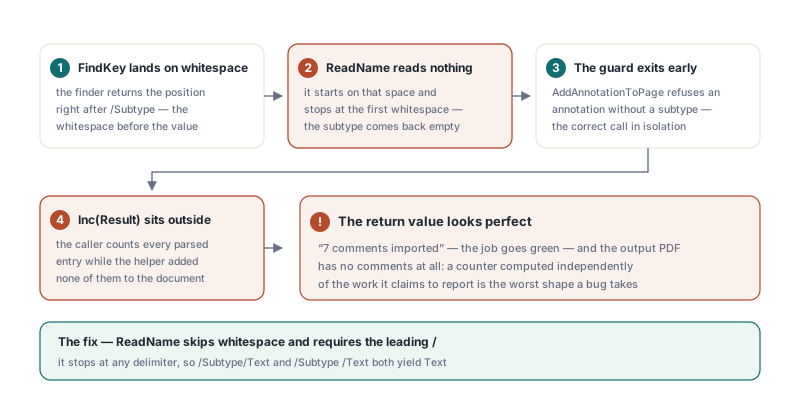
The return value deserves care beyond that, too. An importer that increments for every well-formed dictionary in the /Annots array still over-reports when an entry has an out-of-range 0-based /Page or a missing /Subtype, both of which are skipped. In losLab PDF Library, ImportAnnotationsFromFDFString and ImportAnnotationsFromFDF return the number of annotations actually added, like the XFDF import: the FDF helper AddAnnotationToPage returns a Boolean and the counter only moves on success. Measuring the document is still the stronger check, because it holds no matter which code produced the number, so the sketch below compares AnnotationCount on each page before and after the import
function TotalAnnotations(Lib: TPDFlib): Integer;
var
  Page, Saved: Integer;
begin
  Result := 0;
  Saved := Lib.SelectedPage;
  for Page := 1 to Lib.PageCount do
    if Lib.SelectPage(Page) = 1 then
      Inc(Result, Lib.AnnotationCount);   // per selected page, widgets included
  Lib.SelectPage(Saved);
end;

var
  Lib: TPDFlib;
  Before, Reported, Added: Integer;
begin
  Lib := TPDFlib.Create;
  try
    Lib.LoadFromFile('contract.pdf', '');
    Before := TotalAnnotations(Lib);
    Reported := Lib.ImportAnnotationsFromFDF('review-comments.fdf');
    Added := TotalAnnotations(Lib) - Before;
    if Added <> Reported then   // equal when every entry landed on a page
      Writeln(Format('Importer reported %d, %d landed on a page', [Reported, Added]));
    Lib.SaveToFile('contract-reviewed.pdf');
  finally
    Lib.Free;
  end;
end;
Three more traps behind the first one
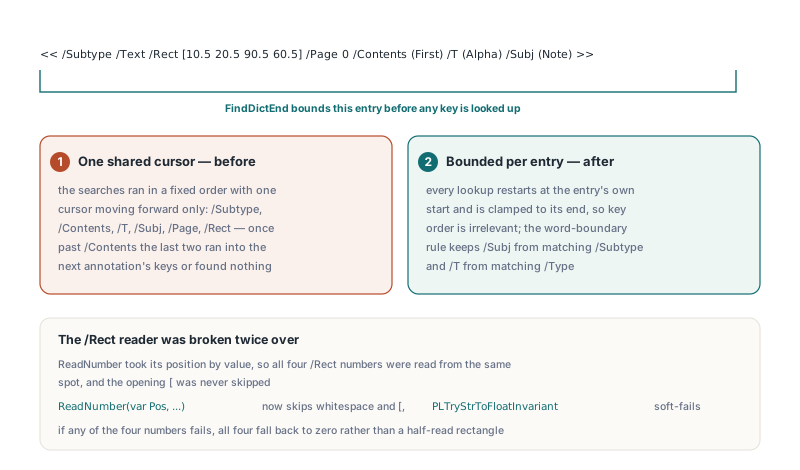
Fixing the subtype alone exposes three further traps in the same kind of parser, each invisible as long as no annotation ever reaches a page. First, a ReadNumber that takes its position as a value parameter reads the same spot four times when it is called for the four /Rect numbers in sequence, and if it does not skip the opening [, in practice it reads nothing at all. Second, a FindKey that shares one forward-moving cursor across all lookups depends on key order. An exporter may write /Subtype, /Rect, /Page, /Contents, /T, /Subj while the importer searches in the order /Subtype, /Contents, /T, /Subj, /Page, /Rect; once the cursor has passed /Contents, the search for /Page and /Rect runs past the current entry and either finds nothing or matches the keys of the next annotation, so the importer cannot even read its own exporter's output. Third, numbers parsed through a routine that follows the system decimal separator, such as PLStrToFloat, break on comma-locale machines. ISO 32000-1 §12.7.7 defines FDF as PDF object syntax, and dictionary keys in PDF are unordered (§7.3.7), so any FDF parser that assumes a key order is wrong by construction, whichever tool produced the file
losLab PDF Library bounds each entry first. FindDictEnd walks from the opening << to its matching >>, tracking nested dictionaries and skipping literal string bodies with their backslash escapes, so a >> inside a comment such as (see section >> 4) cannot end the entry early. Every key lookup then starts at the entry's own start and is limited to its end, which makes key order irrelevant and stops one annotation from borrowing another's /Page. The key match also accepts a delimiter directly after the name, because /Contents(Hi) is as valid as /Contents (Hi), while the word-boundary rule keeps /Subj from matching the start of /Subtype and /T from matching /Type. ReadNumber takes its position as a var parameter, skips whitespace and [, and parses with PLTryStrToFloatInvariant, which fails softly on a malformed token instead of raising. If any of the four rectangle numbers fails, all four fall back to zero rather than producing a half-read rectangle
Why can FDF round-trips shift every annotation by its own height?
Because it is easy to write a rectangle in the wrong coordinate model. An annotation's /Rect is [llx lly urx ury] in default user space (ISO 32000-1 §12.5.2, with rectangles defined in §7.9.5), and FDF carries the same array. GetAnnotRectEx, however, reports Left, Top, Width and Height in the library's drawing coordinates, the space that SetOrigin controls. An exporter that serializes those as [L T L+W T+H] hands the importer four values that, written back verbatim as a PDF rectangle, put the top edge where the lower-left corner belongs, so every round trip moves the annotation up by its own height. The losLab PDF Library exporter copies the annotation's own /Rect numbers, three decimals, dot separator, no exponent, and falls back to the computed rectangle only when the stored array is missing or not four numbers
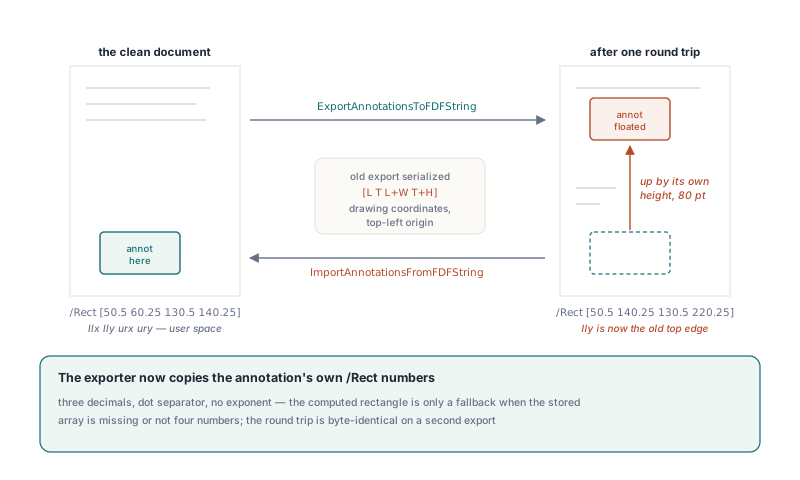
A round-trip test worth copying asserts on the document and on a second export, not on the importer's return value. Note the expected count of 2: AddNoteAnnotation creates a Text annotation plus its Popup, and both travel. The test also runs the export and import under a comma decimal separator, which is where the other half of this story lives
var
  Source, Target: TPDFlib;
  FDF: AnsiString;
  OldSep: Char;
begin
  Source := TPDFlib.Create;
  Target := TPDFlib.Create;
  try
    Source.NewPages(1);                     // now two pages
    Source.SelectPage(2);
    Source.AddNoteAnnotation(50.5, 60.25, 0, 80, 80, 120, 60,
      'Reviewer', 'Check this', 0.25, 0.5, 0.75, 0);
    Target.NewPages(1);

    OldSep := FormatSettings.DecimalSeparator;
    FormatSettings.DecimalSeparator := ',';   // simulate a German or French desktop
    try
      FDF := Source.ExportAnnotationsToFDFString;   // still writes /Rect [50.5 ...
      Target.ImportAnnotationsFromFDFString(FDF);
    finally
      FormatSettings.DecimalSeparator := OldSep;
    end;

    Target.SelectPage(2);
    Assert(Target.AnnotationCount = 2);           // the note and its popup
    Assert(Target.GetAnnotType(1) = 'Text');
    Assert(Target.ExportAnnotationsToFDFString = Source.ExportAnnotationsToFDFString);
  finally
    Target.Free;
    Source.Free;
  end;
end;
The FDF path is built around the annotation's core dictionary. The importer rebuilds each entry with /Type, /Subtype, /Rect, /Contents, /T and /Subj, and the exporter leaves Widget annotations to the form-data methods, where form fields belong. Before relying on FDF for color, flags, border style, popup links or appearance streams, check the broader map of which data travels through which method in the overview of FDF, XFDF and XFA form data interchange, and if you need to inspect what actually arrived, the per-index readers such as GetAnnotType, GetAnnotTitle and GetAnnotContentsEx are covered in outline, annotation and action introspection
How do you read comma-decimal FDF and XFDF files?
For FDF the answer is unambiguous: a comma is not a delimiter in PDF syntax, so a number token that contains exactly one comma and no dot can only be a decimal written on a comma-locale machine. Such files exist, for example /Rect [10,500 20,250 40,750 60,125] from an exporter that formatted numbers with the system locale, and ReadNumber turns that single comma into a dot before parsing. A token with two commas, or a comma and a dot, is rejected rather than guessed at. The reader does not consume exponent notation either, which matches ISO 32000-1 §7.3.3: PDF numbers never use it
XFDF is harder, because in XML attributes the comma is the separator. Standard XFDF (ISO 19444-1) writes rect="50.5,80.25,70.75,100.125" and dashes="4,2", while a locale-dependent writer on a comma-locale system produces rect="50,500 80,250 70,750 100,125" and opacity="0,600". losLab PDF Library reads and writes XFDF numbers invariantly in both directions, and recognizes the legacy shape through XFDFNormalizeLegacyDecimals only when the attribute splits on whitespace into exactly the expected number of tokens (four for rect, one for opacity and width) and every token has the form digits-comma-digits. A standard rect never matches: it is either one token with three commas or tokens that end in a comma. dashes is deliberately left alone, because 4,2 could be two dash lengths or a legacy 4.2, and no rule can tell them apart
const
  // Keys out of exporter order, plus comma decimals from a comma-locale export
  LegacyFDF: AnsiString = '%FDF-1.2'#10'1 0 obj'#10'<< /FDF << /Annots ['#10 +
    '<< /Rect [10,500 20,250 40,750 60,125] /Page 0 /Contents (First) ' +
    '/Subtype /Text /T (Alpha) /Type /Annot >>'#10 +
    '] >> >>'#10'endobj'#10'trailer'#10'<< /Root 1 0 R >>'#10'%%EOF'#10;
var
  Lib: TPDFlib;
begin
  Lib := TPDFlib.Create;               // a fresh document has one page
  try
    Lib.ImportAnnotationsFromFDFString(LegacyFDF);
    Assert(Lib.AnnotationCount = 1);
    Assert(Lib.GetAnnotTitle(1) = 'Alpha');
    // Re-exported as XFDF with dot decimals: rect="10.500 20.250 40.750 60.125"
    Writeln(Lib.ExportAnnotationsToXFDFString);
  finally
    Lib.Free;
  end;
end;
What should an annotation import test actually assert?
A useful import test asserts on the state of the target document, never only on what the importer says about itself; in the silent-zero failure, the return value is the one number that stays intact. Three assertions catch every trap described here: the annotation count on the expected page, one field read back through GetAnnotType or GetAnnotContentsEx, and a second export compared byte for byte with the first. The same discipline applies to any API that rewrites document structure in bulk, including the field consolidation described in merging duplicate form fields: check the resulting tree, not a returned total. The FDF and XFDF annotation methods, with their file and string variants, ship in the losLab PDF Library for Delphi and C++Builder