A Russian invoice run through a recogniser that loads the Cyrillic model but still reads the Chinese character dictionary comes back as rows of perfectly valid Han characters. Every line is well-formed UTF-8, every line lands in the searchable text layer, and a search for any word printed on the page finds nothing. The model did its job. A CTC recogniser never outputs characters, only class numbers, and the dictionary file is the one thing that maps class 1,204 to a glyph
Three related failures sit close by, and a Latin-script demo shows none of them: every line losing its final character, English text arriving without word spacing, and Arabic text boxes coming back in left-to-right order. Each traces to a dictionary rule, a loop boundary or a sort order that is easy to get almost right. All four start at the same point: the step that turns a language tag into a model and a dictionary
RapidOCR language presets in HotPDF: one tag, one pinned pair
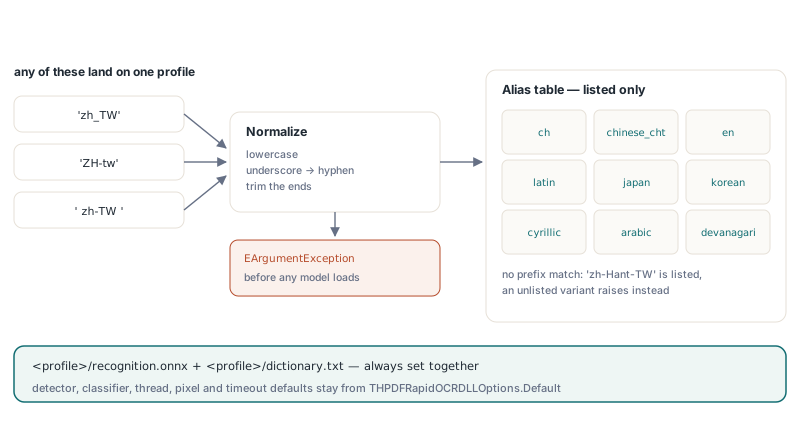
In HotPDF, THPDFRapidOCRDLLOptions.ForLanguage turns a language tag into options that point at <profile>/recognition.onnx and <profile>/dictionary.txt below your model directory. Everything else comes from THPDFRapidOCRDLLOptions.Default: the shared detector, the optional angle classifier, one thread, a 16,777,216-pixel budget per request and a 60-second timeout. The tag is lowercased, underscores become hyphens and surrounding whitespace is trimmed, so 'zh_TW', 'ZH-tw' and ' zh-tw ' resolve to the same profile
Matching runs against an explicit alias list, with no prefix matching. 'zh-Hant-TW' and 'zh-MO' are accepted because they are listed; 'pt-AO' is not, and ForLanguage raises EArgumentException before any file is opened. That strictness is deliberate. A prefix rule would quietly send 'zh-Hant-SG' or some future tag to whichever profile shares its first two letters, and with Chinese the first two letters do not tell you the script
| Profile | Languages | Example tags | Box order in a row |
|---|---|---|---|
ch | Simplified Chinese and English | zh, zh-CN, zh-Hans, chi_sim | Left to right |
chinese_cht | Traditional Chinese | zh-TW, zh-HK, zh-Hant, chi_tra | Left to right |
en | English | en, en-US, en-GB, eng | Left to right |
latin | French, German, Spanish, Portuguese, Italian, Dutch, Turkish | fr, de, es-419, pt-BR, tr | Left to right |
japan | Japanese | ja, ja-JP, jpn | Left to right |
korean | Korean | ko, ko-KR, kor | Left to right |
cyrillic | Russian, Ukrainian, Bulgarian, Belarusian | ru, ru-RU, uk, bg | Left to right |
arabic | Arabic, Persian, Urdu | ar, ar-SA, fa, ur | Right to left |
devanagari | Hindi, Marathi, Nepali | hi, mr, ne | Left to right |
The adapter never downloads anything. Model files are provisioned once with the bundled helper, for example tools/Install-RapidOCRModels.ps1 -Destination C:/OCR/models -Language ch,chinese_cht,cyrillic, or -Language All for all nine profiles. The helper puts the shared detector and classifier at the root filenames Default expects and each profile in its own folder. Engine creation, the DLL boundary and threading are covered in the article on the in-process RapidOCR DLL; with the files in place, a Simplified Chinese scan becomes searchable like this
uses
  SysUtils, HPDFDoc, HPDFRapidOCRRecognition;

procedure MakeChineseScanSearchable(const SourceFile, TargetFile: string);
var
  Doc: THotPDF;
  Engine: IHPDFOCREngine;
  Models: THPDFRapidOCRDLLOptions;
  Layer: THPDFOCRTextLayerOptions;
  Info: THPDFOCRTextLayerInfo;
begin
  // ch/recognition.onnx + ch/dictionary.txt, shared detector and classifier
  Models := THPDFRapidOCRDLLOptions.ForLanguage('zh-CN');
  // models load here; reuse the engine across documents
  Engine := HPDFCreateRapidOCRDLLOCREngine(
    'C:\OCR\Win64\HotPDFRapidOCR.dll', 'C:\OCR\models', Models);
  Doc := THotPDF.Create(nil);
  try
    Doc.AutoLaunch := False;
    if Doc.LoadFromFile(SourceFile) < 1 then
      raise Exception.Create('Cannot load ' + SourceFile);
    Layer := THPDFOCRTextLayerOptions.Default;  // 300 DPI, MinimumConfidence 0.5
    // empty page list = every page; SkipPagesWithText leaves text pages alone
    if not Doc.ApplyLoadedOCRTextLayer([], Engine, Layer, Info) then
      raise Exception.Create(string(Info.Diagnostic));
    Writeln(string(Info.EngineName), ': ', Info.AcceptedWordCount,
      ' lines, ', Info.UniqueScalarCount, ' distinct characters');
    Doc.SaveLoadedDocument(TargetFile);
  finally
    Doc.Free;
  end;
end;
Two numbers in that output need reading carefully. The native pipeline reports one result per detected text line, so AcceptedWordCount counts lines here, and MinimumConfidence is compared with the mean character confidence of the whole line: a line averaging 0.45 is dropped as a unit. UniqueScalarCount is the number of distinct Unicode scalars the text layer had to map into its font and ToUnicode table. A page of Chinese body text should push that figure well past the few dozen scalars a Latin page needs; a count in Latin territory on a Chinese scan usually means the wrong profile is loaded
Why does switching only the recognition model produce garbage?
Because the model and the dictionary are two halves of one lookup table, and only the dictionary knows what the indices mean. Point RecognitionModel at cyrillic/recognition.onnx while CharacterDictionary still names the Chinese file, and the model emits valid Cyrillic indices that the old dictionary translates into random Han characters. ForLanguage always sets both fields together. Hand-built options should follow the same rule: never change one without the other
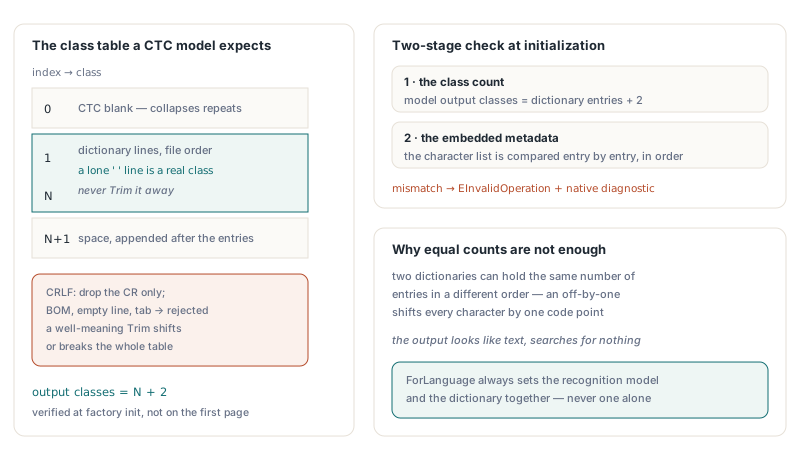
The obvious guard, comparing the dictionary size with the model output width, is necessary and still not enough. Two dictionaries can hold the same number of entries in a different order, and an off-by-one shifts every character by one position. The HotPDF RapidOCR DLL therefore checks twice while the factory initialises the recogniser. The model's output class count must equal the dictionary entries plus two. Then, if the ONNX file embeds a character metadata list, each dictionary line is compared with it in order. Either mismatch makes HPDFCreateRapidOCRDLLOCREngine raise EInvalidOperation with the native diagnostic, so the error surfaces at startup and not in a customer's archive
The "plus two" comes from the class layout. Class 0 is the CTC blank, classes 1 to N are the dictionary lines in file order, and the final class is a space. Some dictionaries carry their own single-space entry as well, and that line has to survive exactly as it is. Here a well-meaning Trim does real damage: it turns the space entry into an empty string and shifts or breaks the table. The DLL strips a trailing carriage return so CRLF files load, and rejects a UTF-8 byte order mark, an empty line, or an entry containing a tab or a stray carriage return
If you maintain your own dictionaries, a pre-flight check in your build or deployment script catches these problems before the engine does. The function below is your own code, written to mirror the rules above
// Your own helper, not a HotPDF API: builds the class table a CTC
// recogniser expects and rejects the dictionary defects the DLL rejects
uses
  SysUtils, IOUtils;

function BuildCTCClassTable(const FileName: string): TArray<string>;
var
  Text, Entry: string;
  Lines: TArray<string>;
  I, Last: Integer;
begin
  Text := TEncoding.UTF8.GetString(TFile.ReadAllBytes(FileName));
  if (Text <> '') and (Text[1] = #$FEFF) then
    raise EArgumentException.Create('Dictionary must be UTF-8 without a BOM');
  Lines := Text.Split([#10]);
  Last := High(Lines);
  if (Last >= 0) and (Lines[Last] = '') then
    Dec(Last);                                   // newline at end of file
  if Last < 0 then
    raise EArgumentException.Create('Dictionary is empty');
  SetLength(Result, Last + 3);
  Result[0] := '';                               // class 0: CTC blank
  for I := 0 to Last do
  begin
    Entry := Lines[I];
    if (Entry <> '') and (Entry[Length(Entry)] = #13) then
      SetLength(Entry, Length(Entry) - 1);       // CRLF: drop the CR only
    if (Entry = '') or (Pos(#9, Entry) > 0) or (Pos(#13, Entry) > 0) then
      raise EArgumentException.CreateFmt('Invalid dictionary line %d', [I + 1]);
    Result[I + 1] := Entry;                      // never Trim: ' ' is a class
  end;
  Result[Last + 2] := ' ';                       // final class: space
  // Length(Result) must equal the model output class count
end;
Greedy CTC decoding and its three boundary traps
Greedy CTC decoding picks the highest-scoring class at each time step, collapses consecutive repeats into one character and drops the blank. The blank is what lets a genuinely doubled letter survive. A recognition model reads a text line as a sequence of narrow vertical slices, and for each slice it outputs a probability for every class. A line containing AA中 might produce the argmax sequence A A blank A 中 space: the first two A steps collapse into one, the blank separates it from the next A, and the output is AA中 with the trailing space intact. Without the blank rule, book and bok would decode identically
A decoder that short invites off-by-one mistakes, and each mistake produces its own recognisable symptom. Stop the inner argmax loop one class early and the space class can never win, so every English or Latin line comes back as one long word and phrase search stops working. Stop the outer loop one time step early and the last character of every line disappears, which on a two-character label is half the text. Forget to let a blank reset the repeat guard and doubled characters collapse: ll in hello, or the reduplicated 谢谢. If you write a decoder for a custom pipeline, these three cases make a compact test set. The HotPDF decoder covers the last class and the last step, keeps blank-separated repeats, and rejects scores that are not finite or fall outside 0 to 1, plus any class count that disagrees with the dictionary
// Illustration for your own pipeline, not a HotPDF API: greedy CTC
// decoding with correct boundaries. Scores holds Steps * Classes
// probabilities, one row per time step
function GreedyCTCDecode(const Scores: array of Single;
  Steps, Classes: Integer; const Characters: array of string): string;
var
  Step, C, Best, Previous: Integer;
  BestScore: Single;
begin
  if (Classes < 3) or (Length(Characters) <> Classes) or
    (Length(Scores) <> Steps * Classes) then
    raise EArgumentException.Create('Model output does not match the dictionary');
  Result := '';
  Previous := 0;                            // class 0 is the CTC blank
  for Step := 0 to Steps - 1 do             // include the last time step
  begin
    Best := 0;
    BestScore := Scores[Step * Classes];
    for C := 1 to Classes - 1 do            // include the last class (space)
      if Scores[Step * Classes + C] > BestScore then
      begin
        Best := C;
        BestScore := Scores[Step * Classes + C];
      end;
    if (Best <> 0) and (Best <> Previous) then
      Result := Result + Characters[Best];
    Previous := Best;                       // a blank resets the repeat guard
  end;
end;
Beam search with a language model can resolve some ambiguous slices that greedy decoding gets wrong, at a real cost in speed and in a second set of files to version. For printed documents rendered at 300 DPI, greedy decoding is the right default, and the decoder is the wrong place to compensate for what the model cannot see. The same applies to character substitution tables. If a model reads an accented letter as its base letter, patching the output with a replacement table repairs one language and breaks another. A wrong character in a searchable layer is worse than a missing one, because search finds the wrong document instead of no document, so the recognised text goes into the PDF exactly as the model produced it
How are text lines ordered for right-to-left Arabic?
The DLL sorts detected text boxes top to bottom, groups boxes into one row when they overlap vertically by at least half the smaller box height, and orders each row left to right, or right to left when RightToLeft is set. The characters inside a recognised line are never reversed. Row grouping matters because detectors often split one visual line into several boxes, a label and a value separated by a wide gap for instance, and a plain top-coordinate sort would interleave them with the next line whenever their tops differ by a pixel or two
The Arabic profile is the only one where ForLanguage sets RightToLeft := True, which makes the DLL order each row by the boxes' right edges, starting from the right margin. That is the whole effect. The text the model returns for a line is already in Unicode logical order, the order an Arabic reader reads and types it, and that is also the order PDF text extraction and search expect. Reversing the string so it "looks right" in the Delphi debugger would break search, copy and paste, and screen readers. Bidirectional display and glyph shaping belong to the PDF viewer
One engine serves one language profile, and there is no automatic script detection. A document that mixes scripts needs one engine per profile, each applied to its own pages. ApplyLoadedOCRTextLayer takes an explicit page list and commits each call as its own transaction, so a failure on the Arabic pages rolls back that call without touching the Chinese layer already written
uses
  SysUtils, HPDFDoc, HPDFRapidOCRRecognition;

function CreateRapidEngine(const Tag: string): IHPDFOCREngine;
var
  Models: THPDFRapidOCRDLLOptions;
begin
  // raises EArgumentException for an unlisted tag, before any model loads
  Models := THPDFRapidOCRDLLOptions.ForLanguage(Tag);
  Models.MaxPixels := 33554432;          // room for A3 pages at 300 DPI
  Result := HPDFCreateRapidOCRDLLOCREngine(
    'C:\OCR\Win64\HotPDFRapidOCR.dll', 'C:\OCR\models', Models);
end;

procedure OCRMixedArchive(Doc: THotPDF);
var
  Chinese, Arabic: IHPDFOCREngine;
  Layer: THPDFOCRTextLayerOptions;
  Info: THPDFOCRTextLayerInfo;
begin
  Chinese := CreateRapidEngine('zh-TW');  // chinese_cht profile
  Arabic := CreateRapidEngine('ar-SA');   // arabic profile, RightToLeft = True
  Layer := THPDFOCRTextLayerOptions.Default;
  if not Doc.ApplyLoadedOCRTextLayer([0, 1, 2], Chinese, Layer, Info) then
    raise Exception.Create(string(Info.Diagnostic));
  if not Doc.ApplyLoadedOCRTextLayer([3], Arabic, Layer, Info) then
    raise Exception.Create(string(Info.Diagnostic));
end;
The MaxPixels line is there for a reason. The default budget of 16,777,216 pixels per request covers A4 and US Letter at 300 DPI with room to spare. An A3 sheet at 300 DPI works out to about 3508 by 4961 pixels, roughly 17.4 million, so that request is refused and Info.Diagnostic reports an invalid request or pixel budget. Raise MaxPixels up to the 67,108,864 ceiling, or lower THPDFOCRTextLayerOptions.DPI for large formats. Right-to-left ordering goes through the DLL export HPDFRapidOCRSetReadingDirection, which the adapter looks up only when RightToLeft is set; a DLL build without that export still serves the left-to-right profiles, and creating an Arabic engine with it raises EArgumentException naming the missing export
Pinned model packs and what a custom pair must pass
The HotPDF RapidOCR DLL links a statically built ONNX Runtime, so it reads the ONNX file format versions that runtime understands and nothing newer. Recent model exports can target a newer format; such a file is rejected at engine creation with a native diagnostic. That pairing is why each language pack points at one specific recogniser and dictionary that load and pass the class checks under the bundled runtime, and why the packs are never "latest"
Install-RapidOCRModels.ps1 enforces the pairing on disk. Every file in its manifest carries a SHA256 hash. An existing file with a different hash stops the install and is left in place for you to move or remove, and each download is written under a temporary name and moved into position only after its hash matches. That blocks the quiet version of the dictionary problem: someone copies a newer recognition.onnx into a profile folder by hand, the class count happens to match, and the first sign of trouble is a customer saying search cannot find words they can plainly see. If you install with -SkipClassifier, set UseAngleClassifier := False in the options, because Default expects the classifier file and engine creation checks that it exists
The recogniser also checks the model's input shape at load time. It accepts NCHW float input with a fixed height of 32 or 48 pixels, or a dynamic height, which it runs at 48. A model exported with any other fixed height fails engine creation with "Unsupported recognition model input or output shape"
For a script none of the nine profiles cover, RecognitionModel and CharacterDictionary can point at your own files, and every check above still applies. A mismatched pair fails at engine creation, in your test run. For pages where no RapidOCR profile fits, the Tesseract adapter for searchable PDF plugs into the same ApplyLoadedOCRTextLayer call, and for machine-printed ASCII forms the built-in template-matching OCR engine needs no model files at all
Language presets, the native RapidOCR adapter and the OCR text layer are all included in the HotPDF Delphi PDF Component for Delphi, C++Builder and Windows FPC/Lazarus projects