Here is a mistake that a hand-written JBIG2 reader makes on the first unusual file it meets. It parses the file header, parses the first segment header, reads the four-byte data length, and takes that many bytes as the segment body. On most .jb2 files that is exactly right. On a file whose flags byte has bit 0 cleared, those "body" bytes are really the second, third and fourth segment headers, and the arithmetic decoder turns them into a bitmap of noise or runs off the end of the buffer. The file is not broken. It uses the random-access organization from ITU-T T.88 Annex D.2, where every segment header comes first and all segment data follows afterwards, in the same order
Random-access files are rare. They come out of archival and document-imaging systems that want a reader to see every page and dictionary dependency before it touches a compressed byte. If a conversion job mixes files from such a source with ordinary scans, one random-access file can sit in the middle of a batch that is otherwise all sequential. The decoder that reads them is the same native Pascal decoder that handles JBIG2 custom Huffman tables and canonical prefix codes, so the coding side is unchanged; only the order in which segments are found differs
Three file layouts behind one flags byte
PDF Library for Delphi reads standalone JBIG2 files through TPLJBIG2Decoder in the PDFlibJBIG2 unit, and the decoder works out the layout from the file header on its own. T.88 Annex D allows the same segments to be arranged three ways: sequential (D.1) puts each header directly in front of its data, random-access (D.2) puts all headers first and all data after them, and embedded (D.3) is the headerless form used inside other containers. A standalone file starts with the eight-byte identifier 97 4A 42 32 0D 0A 1A 0A, then one flags byte, then a four-byte page count unless the flags say the count is unknown
Bit 0 of that flags byte picks the organization: 1 means sequential, 0 means random-access. Bit 1 set means the number of pages is unknown and the four-byte count is absent, so the first segment header starts at byte 9 instead of byte 13. Bits 2 to 7 are reserved; the decoder accepts files that set them instead of rejecting them, because a stray reserved bit says nothing about whether the segments themselves are readable
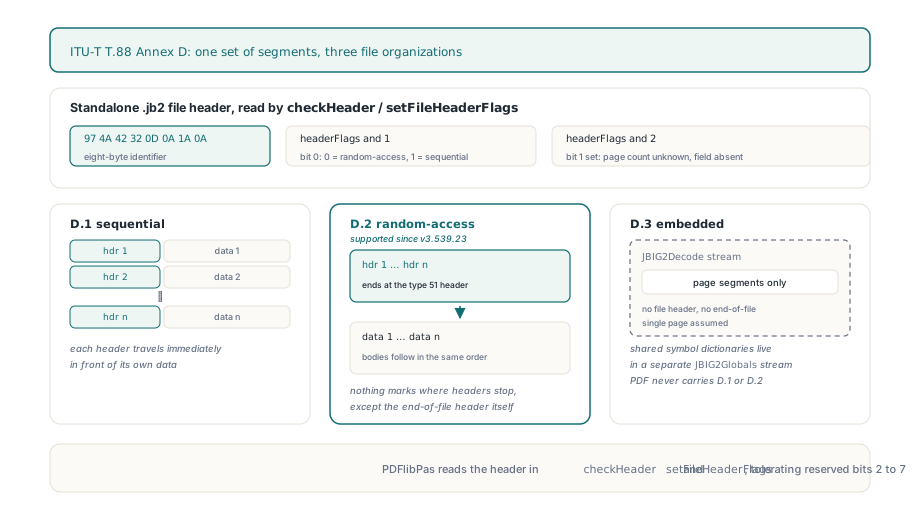
PDF itself never carries the random-access layout. A JBIG2Decode image stream, described in ISO 32000-1 §7.4.7, holds only page segments in embedded form, with shared symbol dictionaries moved into a separate JBIG2Globals stream and no file header, end-of-page or end-of-file segments. When the decoder does not find the eight-byte identifier, it treats the input as exactly that kind of stream: sequential, one page. Going the other way, when PDF Library for Delphi exports a JBIG2Decode image as a native .jb2 file, it writes the flags byte $03 (sequential, page count unknown) and appends an end-of-file segment header. So random access only ever arrives from outside, as a standalone file handed to TPLJBIG2Decoder directly, usually on its way to being converted or recompressed for PDF with the JBIG2 encoder backends in PDFlibPas
Why can't you read a random-access file in file order?
Because nothing in the byte stream marks where the header block ends and the data block begins, except the end-of-file segment header (type 51) itself. JBIG2 segment headers have no fixed size. The referred-to segment count is either a three-bit short form or a long form followed by a retention bitmap; each referred-to segment number takes one, two or four bytes depending on how large the current segment's own number is; the page association field is one byte or four. A reader has to parse every field of a header just to learn where the next one starts
A sequential reader that walks the file in order gets the first header right and everything after it wrong. Worse, it may not notice for a while: a generic region decoder fed header bytes produces pixels, not an error, until some later length or reference check finally trips. Our view is that a decoder which does not index headers first should refuse random-access files outright. A clear rejection costs one file in a batch; a plausible-looking but wrong bitmap can end up in an archive and stay there
Indexing every header before the first body
When the flags byte says random-access, PDF Library for Delphi makes one pass over the header block before decoding anything. Each header is parsed in full and then thrown away; the only thing kept is its byte offset in the file. The compressed data is never copied into a reordered second buffer, which matters on large archival scans where the data block can be most of the file. The pass stops at the first end-of-file header, and at that point the read position sits on the first byte of the first segment's data
A random-access file has less redundancy than a sequential one, so the pre-scan is strict. It rejects the file when:
- a header is cut off by the end of the buffer, reported as
JBIG2 truncated random-access header at byte Nwith the offset where that header began - segment numbers do not strictly increase (compared as unsigned values), because two headers claiming the same number make a later region's referred-to list ambiguous
- a data length has its top bit set, which includes the
0xFFFFFFFF"unknown length" marker; in this layout there is no other way to find where the next body starts, so the decoder refuses it immediately instead of scanning ahead for an end marker - the end-of-file header declares any data, or never appears at all (
JBIG2 random-access file is missing its end-of-file header) - the declared lengths add up to more than the bytes that remain, or to fewer
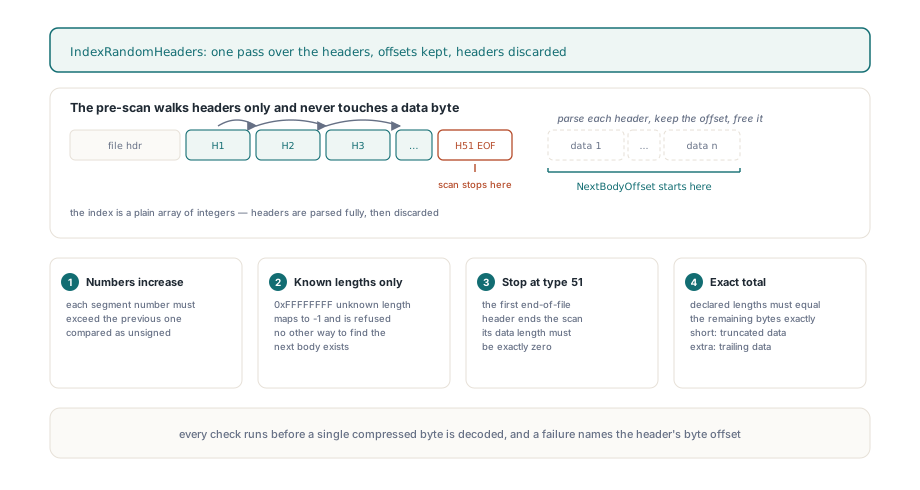
The last rule is the one people trip over. A single extra byte after the final body fails with JBIG2 trailing random-access data. That looks harsh next to the sequential path, where decoding simply stops at the end-of-file segment and anything after it is ignored. The asymmetry has a reason. In sequential layout each header sits right next to its own data, so junk at the end cannot have shifted anything. In random-access layout the headers are the only map of the data block, and if the lengths do not add up, the decoder cannot tell harmless padding from a byte lost or added much earlier that has shifted every body after it
Why does a byte-counted loop drop the last end-of-page segment?
A loop that runs "while there are bytes left" ends too early on a random-access file, because the data runs out before the header index does. End-of-page (type 49) and end-of-file segments carry zero bytes of data and normally come last. Once the final region body has been consumed, the read position is exactly at the end of the buffer; a byte-counted loop exits there, and the zero-length end-of-page segment never gets dispatched, which leaves the page unfinished
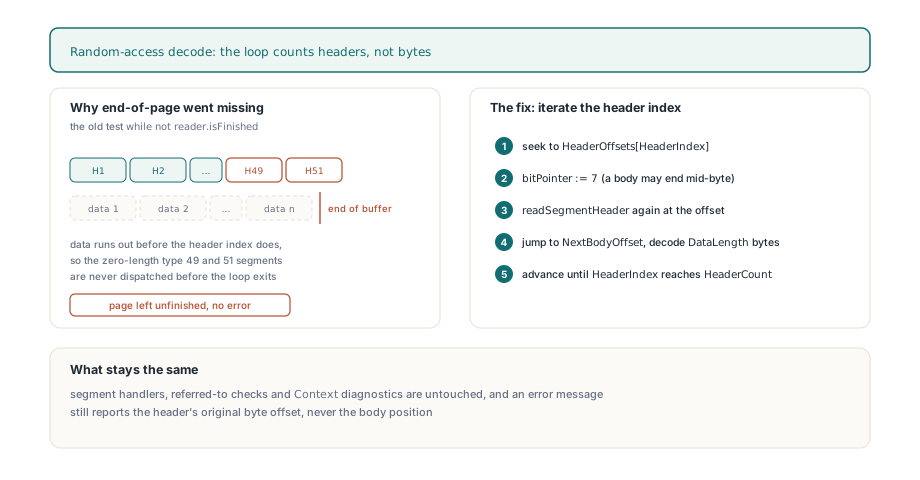
So for random-access files the decoder counts headers, not bytes. Each step jumps back to the next indexed header, realigns to a byte boundary (an arithmetic-coded body can end in the middle of a byte), parses the header again, then jumps forward to where the next body starts and advances past it by the declared length. A body whose decoder finishes early is skipped to its declared end; one that reads past it is rejected. From there the segment goes through the same handlers and reference checks as in a sequential file. Errors raised while decoding a body carry the header's original position, in the form JBIG2 segment N (type T) at byte B: ..., so the offset in LastError points at something you can find in a hex editor
Loading a random-access .jb2 file in Delphi
Application code does not change with the organization. TPLJBIG2Decoder.LoadFromByteArray detects the file header and layout, returns False on any rejected input with the reason in LastError, and exposes the decoded page through Width, Height and GetScanline, which fills one byte per pixel with 1 for black
uses
  SysUtils, Classes, PDFlibJBIG2;

function ReadJb2(const FileName: string): TJBIG2ByteArray;
var
  FS: TFileStream;
begin
  FS := TFileStream.Create(FileName, fmOpenRead or fmShareDenyWrite);
  try
    SetLength(Result, FS.Size);
    if Length(Result) > 0 then
      FS.ReadBuffer(Result[0], Length(Result));
  finally
    FS.Free;
  end;
end;

function CountBlackPixels(const FileName: string): Integer;
var
  Decoder: TPLJBIG2Decoder;
  Row: TJBIG2ByteArray;
  X, Y: Integer;
begin
  Result := 0;
  Decoder := TPLJBIG2Decoder.Create;
  try
    // Sequential and random-access standalone files take the same call
    if not Decoder.LoadFromByteArray(ReadJb2(FileName)) then
      raise Exception.Create('JBIG2 rejected: ' + Decoder.LastError);
    for Y := 0 to Decoder.Height - 1 do
      if Decoder.GetScanline(Y, Row) then
        for X := 0 to Decoder.Width - 1 do
          if Row[X] = 1 then
            Inc(Result);
  finally
    Decoder.Free;
  end;
end;
If you want to know which layout a file uses, for logging or for sorting a corpus before a conversion run, read the flags byte yourself. The library does not expose the organization it detected, and nine bytes are all you need. The helper below is something to add to your own code; it simply restates the T.88 header rules:
type
  TJb2Layout = (jlNoFileHeader, jlSequential, jlRandomAccess);

// Your own helper, not part of PDFlibJBIG2: classifies a buffer by its T.88 file header
function DetectJb2Layout(const Data: TJBIG2ByteArray;
  out PageCountKnown: Boolean): TJb2Layout;
const
  Signature: array[0..7] of Byte = ($97, $4A, $42, $32, $0D, $0A, $1A, $0A);
var
  I: Integer;
begin
  Result := jlNoFileHeader;          // e.g. an embedded stream lifted out of a PDF
  PageCountKnown := False;
  if Length(Data) < 9 then
    Exit;
  for I := 0 to 7 do
    if Data[I] <> Signature[I] then
      Exit;
  PageCountKnown := (Data[8] and 2) = 0;   // bit 1 set: no four-byte page count
  if (Data[8] and 1) = 0 then
    Result := jlRandomAccess
  else
    Result := jlSequential;
end;
Batch jobs: padded buffers and rejected files
The trailing-data rule is where batch code tends to go wrong, and when a file that opens elsewhere is rejected this way, look at the buffer before the file. A .jb2 pulled from a database BLOB column, a fixed-size network read or a container format with alignment padding can arrive with a few zero bytes after the real end. A sequential file shrugs that off. A random-access file with the same padding fails with JBIG2 trailing random-access data, and so does a buffer cut a few bytes short, which fails as truncated. Pass exactly the file's bytes, sized from the source's real length, never from a chunk size or a capacity
A rejected file also leaves nothing behind. LoadFromByteArray resets Width, Height and the scanlines before it starts decoding, so a failed call reports zero dimensions rather than the previous file's page, and the same decoder instance can go straight on to the next file:
procedure DecodeBatch(const Files, Log, Quarantine: TStrings);
var
  Decoder: TPLJBIG2Decoder;
  I: Integer;
begin
  Decoder := TPLJBIG2Decoder.Create;
  try
    for I := 0 to Files.Count - 1 do
      if Decoder.LoadFromByteArray(ReadJb2(Files[I])) then
        Log.Add(Format('%s: %d x %d', [Files[I], Decoder.Width, Decoder.Height]))
      else
      begin
        // Width and Height are 0 here; nothing from the previous file survives
        Log.Add(Files[I] + ': ' + Decoder.LastError);
        if Pos('trailing random-access data', Decoder.LastError) > 0 then
          Quarantine.Add(Files[I]);   // check how the bytes were stored before blaming the file
      end;
  finally
    Decoder.Free;
  end;
end;
Checking this in your own pipeline does not need rare sample files. Reorganize a sequential .jb2 into random-access layout, keeping every header and every compressed byte, move the end-of-page and end-of-file headers to the end of the header block, and the decoded pixels must match the sequential original exactly, both with and without the page count field. Then feed it every truncated prefix, a duplicated segment number, one extra trailing byte and a 0xFFFFFFFF length; each should return False with Width and Height at zero
What the decoder returns, and what it expects
Random access here is a property of the file layout. TPLJBIG2Decoder returns the first page's bitmap whichever organization the file uses, and Width and Height describe that page. Every segment must declare its data length; T.88 lets an immediate generic region use the 0xFFFFFFFF marker, and the decoder rejects that marker in either layout with unknown or oversized segment length is not supported. Custom Huffman prefix lengths and table-entry counts are capped the same way they are in sequential files
Decoding JBIG2 is one stage of a longer image path that also covers PDF image extraction, recompression and JBIG2 encoding; the PDF Library for Delphi product page covers the rest of that pipeline and the supported image formats