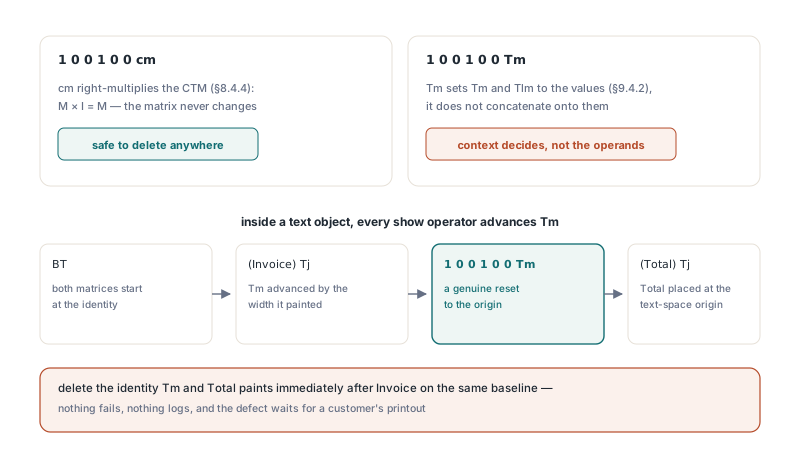
Take a content stream a report generator might write, BT (Invoice) Tj 1 0 0 1 0 0 Tm (Total) Tj ET, and strip the 1 0 0 1 0 0 Tm because its six numbers spell the identity matrix. Render the result and "Total" no longer starts at the text-space origin. It starts where "Invoice" ended, on the same baseline. An identity Tm is redundant only while the text matrix and the text line matrix already hold the identity: directly after BT, or directly after another identity Tm
The deletion is tempting because the same six numbers really are dead weight in front of cm. A content-stream optimizer that treats the two operators alike will shrink plenty of streams correctly. Then it meets a generator that uses an identity Tm as a carriage return, and text moves
Why is 1 0 0 1 0 0 Tm not always a no-op?
The two operators do different arithmetic. ISO 32000-1 §8.4.4 defines cm as concatenating its operand with the current transformation matrix; multiply any matrix by the identity and you get the same matrix back, so 1 0 0 1 0 0 cm can be deleted wherever it appears. Tm is an assignment. Under §9.4.2 it sets both the text matrix and the text line matrix to its operands and throws away whatever they held, so whether it changes anything depends entirely on the operators in front of it
§9.4.1 says BT starts both matrices at the identity. From there, almost everything inside a text object moves at least one of them. Td, TD, T* and a non-identity Tm reposition the text line matrix. Every text-showing operator (Tj, TJ, ' and ") advances the text matrix by the width of the glyphs it just painted, and the last two start a new line first. Once any of those has run, an identity Tm is a genuine jump back to the origin. The invoice stream above depends on that jump
Tracing a stream by hand settles it quickly. Feed the invoice example through the content-stream CTM and text matrix state tracker and the record shows cm concatenating onto the CTM while Tm overwrites both text matrices — two different update rules hiding behind identical operands
How PDF Library for Delphi decides which identity Tm to drop
PDF Library for Delphi drops every identity cm during its peephole pass, and drops an identity Tm only when a backward scan from that operator reaches BT or another identity Tm before it meets anything that could have moved the text matrices. The test for "identity" is numeric: the operator needs exactly six number operands equal to 1, 0, 0, 1, 0, 0, so 1.0 0 0 1.0 0 0 Tm qualifies as well. Walking backward, the scan puts every operator it meets into one of two groups:
- Stop and keep the Tm:
Td,TD,T*, a non-identityTm,Tj,TJ,',",ET, any operator the parser does not recognize, or the start of the stream - Step over and keep scanning: operators that never touch the text matrix or the text line matrix, such as
Tf,Tc, color setters,gs, marked-content operators,Doandcm
An earlier identity Tm ends the scan in favor of deletion whether the optimizer is keeping it or has already scheduled it for removal. Either way it left both matrices at the identity, which is the same state BT leaves behind. That is why a run of three identity Tm operators straight after BT collapses to nothing
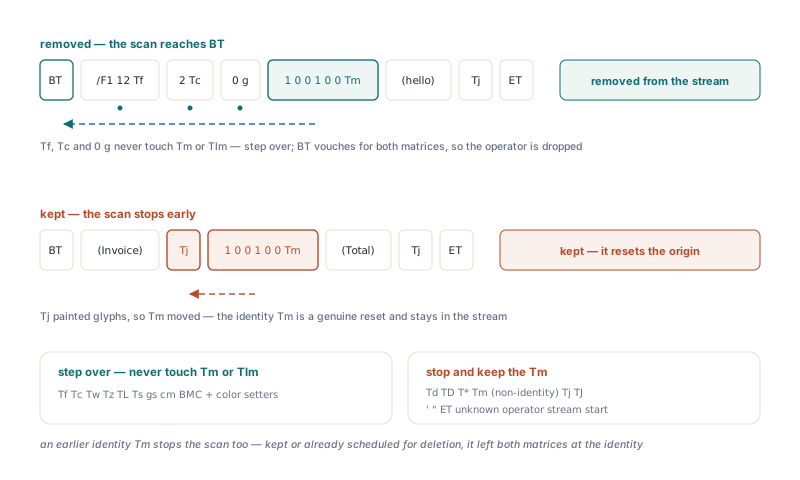
The conservative stops are deliberate. An unknown operator could be a vendor extension that does anything, so the scan refuses to reason past it. After ET there is no open text object, and an identity Tm sitting there has no BT vouching for the matrix values. The scan also looks at one content stream at a time. That matters for pages whose /Contents is an array: PDF lets a text object start in one stream and continue in the next, so a layer that opens in the middle of a text object, with no BT of its own, keeps its identity Tm even when the previous layer would have made it redundant
We think that is the right side to err on. Tracking matrices across stream boundaries, or simulating unknown operators, would recover maybe fourteen bytes of uncompressed text per odd file. Getting it wrong moves a glyph on a printed invoice. The cost and the risk are not in the same league
One knock-on effect is worth knowing because it changes what you see in the output. The same pass also removes text objects with nothing inside, so BT 1 0 0 1 0 0 Tm ET disappears completely: the identity Tm goes first, and the BT/ET pair it leaves behind is empty
Running the optimizer on a content-stream snippet
The optimizer works on the same parsed TPDFContentProgram model you would use to edit page text at the instruction level, as in the character-to-content-byte mapping walkthrough. That makes it easy to try the rule on a string before you trust it with a whole document. The helper below parses a decoded stream, runs TPDFContentPeepholeOptimizer, and emits the result one instruction per line. Setting CanonicalNumbers before Parse mirrors the save-time pass, which rewrites every number at a fixed precision
uses
  PDFlibContentModel, PDFlibContentOptimize;

function OptimizeSnippet(const Source: AnsiString): AnsiString;
var
  Prog: TPDFContentProgram;
  Optimizer: TPDFContentPeepholeOptimizer;
begin
  Result := Source;
  Prog := TPDFContentProgram.Create;
  try
    Prog.CanonicalNumbers := True; // same number handling as the save pass
    if not Prog.Parse(Source) then
      Exit; // gross structural damage: leave the bytes alone
    Optimizer := TPDFContentPeepholeOptimizer.Create(Prog);
    try
      Optimizer.Run; // returns the number of instructions removed
    finally
      Optimizer.Free;
    end;
    Result := Prog.Emit; // one instruction per line, #10 separated
  finally
    Prog.Free;
  end;
end;

// Removed: Tm directly after BT, the second of two identity Tm in a row
//   OptimizeSnippet('BT /F1 12 Tf 1 0 0 1 0 0 Tm (hello) Tj ET')
// Kept: Tm after Td, after Tj, after a non-identity Tm, or outside BT
//   OptimizeSnippet('BT (Invoice) Tj 1 0 0 1 0 0 Tm (Total) Tj ET')
Run the invoice stream through it and the identity Tm survives, because the backward scan hits Tj long before it reaches BT. Put /F1 12 Tf, 2 Tc and 0 g between BT and the identity Tm and it still goes, since none of those touch the text matrices. The interesting case is BT 10 20 Td 1 0 0 1 0 0 Tm 1 0 0 1 0 0 Tm. It loses exactly one operator. The first identity Tm undoes the move that Td made, and only the second one is redundant
Parse returns False only on gross damage such as an unterminated string or dictionary. Unknown operators parse fine and stay in the program, where they act as hard stops for the scan
When does the peephole optimizer actually run?
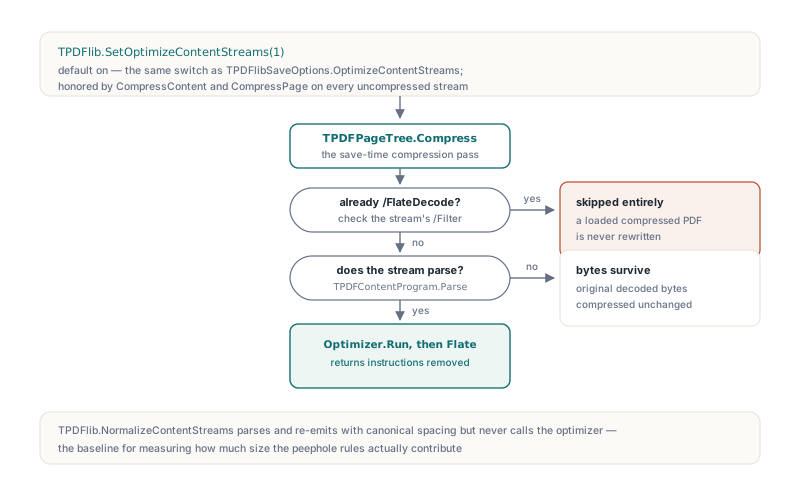
The optimizer runs only inside the compression pass, and only on page content streams that are not already Flate-compressed. TPDFlib.SetOptimizeContentStreams(1) is the default, and the same switch appears as the OptimizeContentStreams field of TPDFlibSaveOptions; CompressContent and CompressPage both honor it. A stream whose /Filter is already /FlateDecode is skipped entirely, so loading a typical compressed PDF and saving it again leaves its operators exactly as they were. Streams stored uncompressed get decoded, optimized and then Flate-compressed. If a stream fails to parse, its original decoded bytes are compressed unchanged
var
  Lib: TPDFlib;
  Options: TPDFlibSaveOptions;
begin
  Lib := TPDFlib.Create;
  try
    if Lib.LoadFromFile('report.pdf', '') <> 1 then
      Exit;
    // Uncompressed page streams go through the peephole rules, then Flate
    Lib.SetOptimizeContentStreams(1);
    Lib.CompressContent;
    Lib.SaveToFile('report-optimized.pdf');

    // The same choice through the bundled save options; False opts out
    Options.CompressContent := True;
    Options.CompressFonts := True;
    Options.CompressImages := True;
    Options.Linearize := False;
    Options.KeepModDate := False;
    Options.OptimizeContentStreams := False;
    Options.GarbageCollect := False;
    Options.PackObjectStreams := True;
    Lib.SaveToFileOptions('report-plain.pdf', Options);
  finally
    Lib.Free;
  end;
end;
Leave the default on. Every transform in the pass is output-equivalent, and the identity-matrix rule goes after a pattern many generators emit, opening every text object with BT 1 0 0 1 0 0 Tm. Turning it off makes sense mainly when you want to diff your own uncompressed output against what you wrote, or when you need a baseline. For that baseline, TPDFlib.NormalizeContentStreams parses and re-emits content with canonical spacing and numbers but never calls the optimizer, so the size gap between a normalized save and an optimized save is what the peephole rules contributed. Expect it to be modest next to the bigger wins described in PDF file size optimization with font subsetting
A test that covers one shape does not define the rule
A test that feeds BT 1 0 0 1 0 0 Tm (hello) Tj ET to an optimizer and asserts that no Tm remains pins one shape: an identity Tm directly after BT gets removed. It says nothing about an identity Tm after Td or after shown text. Reading that single assertion as "identity Tm is always removable" is an easy mistake, and a costly one, because the sample passes either way. Tests for any rule like this one need the kept shapes written down next to the removable ones
The helper below counts the Tm operators that survive, then checks a table of inputs. Swap ExpectTm for your test framework's assertion; it is not part of the library
uses
  SysUtils, PDFlibContentModel, PDFlibContentOps, PDFlibContentOptimize;

function TmCountAfterOptimize(const Source: AnsiString): Integer;
var
  Prog: TPDFContentProgram;
  Optimizer: TPDFContentPeepholeOptimizer;
  I: Integer;
begin
  Result := -1; // -1 signals a parse failure
  Prog := TPDFContentProgram.Create;
  try
    if not Prog.Parse(Source) then
      Exit;
    Optimizer := TPDFContentPeepholeOptimizer.Create(Prog);
    try
      Optimizer.Run;
    finally
      Optimizer.Free;
    end;
    Result := 0;
    for I := 0 to Prog.Count - 1 do
      if Prog[I].Op = coTextMatrix then
        Inc(Result);
  finally
    Prog.Free;
  end;
end;

// Your own check helper, suggested here; replace with a real assertion
procedure ExpectTm(const Source: AnsiString; Expected: Integer);
var
  Actual: Integer;
begin
  Actual := TmCountAfterOptimize(Source);
  if Actual <> Expected then
    raise Exception.CreateFmt('%s: expected %d Tm, got %d',
      [string(Source), Expected, Actual]);
end;

procedure CheckIdentityTmRule;
begin
  // Removable shapes
  ExpectTm('BT /F1 12 Tf 1 0 0 1 0 0 Tm (hello) Tj ET', 0);
  ExpectTm('BT 1 0 0 1 0 0 Tm 1 0 0 1 0 0 Tm (a) Tj ET', 0);
  ExpectTm('BT /F1 12 Tf 2 Tc 0 g 1 0 0 1 0 0 Tm (a) Tj ET', 0);
  // Shapes that must keep the identity Tm
  ExpectTm('BT (Invoice) Tj 1 0 0 1 0 0 Tm (Total) Tj ET', 1);
  ExpectTm('BT 10 20 Td 1 0 0 1 0 0 Tm 1 0 0 1 0 0 Tm (a) Tj ET', 1);
  ExpectTm('BT 2 0 0 2 5 5 Tm (a) Tj 1 0 0 1 0 0 Tm (b) Tj ET', 2);
  ExpectTm('1 0 0 1 0 0 Tm (a) Tj', 1);    // no enclosing BT
  ExpectTm('BT ET 1 0 0 1 0 0 Tm', 1);     // after ET
end;
The last two rows look silly until you remember that layered /Contents arrays produce exactly those fragments. A stream that begins mid-text-object has no BT, and an identity Tm after ET belongs to no text object at all. Both stay. The empty BT ET pair in the final row is removed by the empty-text-object rule, which is why the count checks Tm operators instead of comparing whole strings
What the rule gives up is the occasional identity Tm in the middle of a text object, a few bytes per page before Flate even sees them. What it buys is a guarantee the optimizer's design rests on: no transform in the pass changes the visible page. A size optimizer that moves text is a rendering bug with a good compression ratio
If you generate or post-process PDF content in Delphi or C++Builder, the PDF Library for Delphi and C++Builder ships the content-stream parser, this peephole pass and the save options shown above, along with NormalizeContentStreams for producing a clean, unoptimized baseline to compare against