The attribute axis="rowAxis" on a pivotField element reads like perfectly sensible XML, and a reader that maps it to "row field" will load the pivot with every field on the right axis. Run the same part through a validator built from the ECMA-376 Part 1 §18.10 schema and it fails on the first attribute: ST_Axis has exactly four tokens, axisRow, axisCol, axisPage and axisValues, and rowAxis is not one of them. A pivot writer has to satisfy the schema rather than its own reader, because the people opening the file use Excel and their own parsers
Pivot field definitions are full of rules like that one. Three tend to slip past a round-trip test: the enumeration tokens, the requirement that an items element is never empty, and the trailing subtotal entries Excel lists after the data items. Two more sit on the reading side, in attributes Excel leaves out because they hold their schema default. The rest of this article walks through each rule, shows what the XML has to look like, and shows the Delphi calls that produce it
Why a round trip cannot catch a wrong axis token
A round trip proves that the writer and the reader agree with each other, and nothing more. If the reader accepts both axisRow and rowAxis, a writer that emits the wrong one passes every save-then-load check you can write, because the reader repairs the mistake on the way back in. The fault only shows up when a stricter consumer opens the part: a schema validator, a parser generated from the XSD, or Excel deciding the part needs repair
HotXLS splits the two sides on purpose. The XLSX writer emits only the four ST_Axis tokens, while the pivot reader also maps the English-looking spellings rowAxis, colAxis, pageAxis and dataAxis to the matching axis, so files from producers that use them still load with their layout intact. Output is held to the schema; input only has to be recognizable. The reverse, a strict reader paired with a sloppy writer, would at least fail loudly in your own tests; a forgiving reader paired with a sloppy writer fails nowhere you can see
<!-- invalid: rowAxis is not an ST_Axis value, and CT_Items may not be empty -->
<pivotField axis="rowAxis" defaultSubtotal="1"><items count="0"></items></pivotField>

<!-- valid: ST_Axis token, real items, trailing default subtotal -->
<pivotField axis="axisRow" defaultSubtotal="1">
  <items count="4"><item x="0"/><item x="1"/><item x="2" h="1"/><item t="default"/></items>
</pivotField>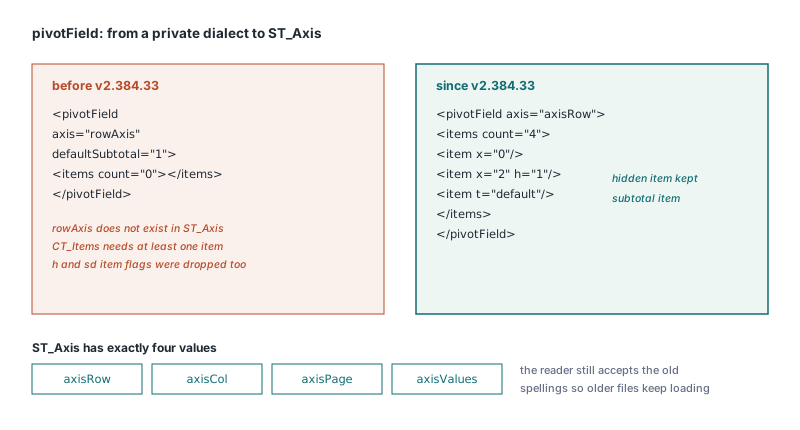
What CT_PivotField expects beyond the axis
CT_PivotField has three more requirements that are easy to drop. A field aggregated in the values area must say so on its own definition with dataField="1", even though the <dataFields> list already references it. HotXLS sets that flag on every pivot field that an entry in DataFields points to, so a field added with AddDataFieldByName is marked in both places
The second rule is structural. CT_Items requires at least one item child, which makes <items count="0"></items> invalid even though it is well-formed XML and parses everywhere. When a field has no items, HotXLS leaves the whole items element out. The third rule is about state on each item: a hidden member carries h="1" and a member with collapsed details carries sd="0". Both come from TXLSPivotItem.IsHidden and TXLSPivotItem.IsDetailHidden and are written on every save, so a filter set in code survives into Excel
Trailing subtotal items and the count trap
When a field has items, Excel follows the data items with one extra item per subtotal function, typed with ST_ItemType. The automatic subtotal is <item t="default"/>; explicit functions use sum, countA, avg, max, min, product, count, stdDev, stdDevP, var and varP. These entries carry no x index into the cache, and they are included in the count attribute of items. A writer that leaves them out produces an items list that no longer matches the subtotal flags on the same element
HotXLS derives the trail from TXLSPivotField.Subtotals at save time: one t="…" item per function in the set, in enumeration order, added to the count, plus the matching sumSubtotal="1"-style attribute on the field. Fields created by AddPivotTable start with an empty set, which writes defaultSubtotal="0" and no trailing item at all. For generated reports, leave the set empty: subtotal rows change the height of the pivot and shift anything placed below it. Add functions to Subtotals only on the fields where a reader needs the extra rows
The naming deserves a second look before you pick a function. xlpsCount maps to countA, which counts all non-empty entries, and xlpsCountNums maps to count, which counts numbers only. Anyone who reads "count" in the XML and reaches for xlpsCount gets the other function
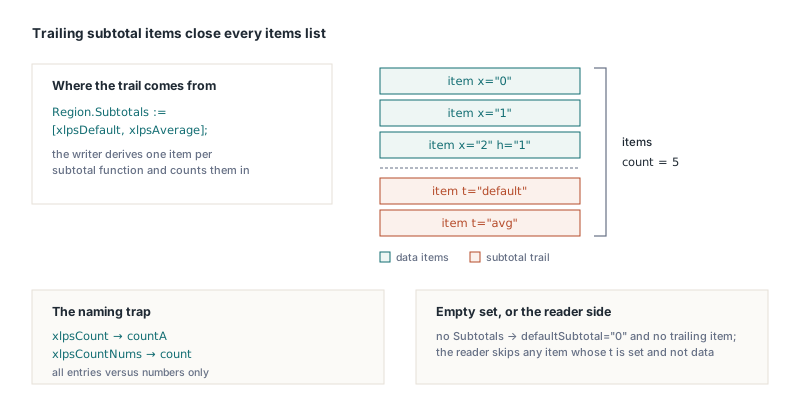
The program below builds a pivot from an existing data sheet with a row field, a column field and one value field. The Region field gets the automatic subtotal plus an average, which produces two trailing items after its data items and dataField="1" on Revenue
uses
  SysUtils, lxHandleX, lxPivot;

var
  Book  : TXLSXWorkbook;
  Sheet : TXLSXWorksheet;
  Pivot : TXLSPivotTable;
  Region: TXLSPivotField;
begin
  Book := TXLSXWorkbook.Create;
  try
    Book.Open('orders.xlsx');
    Sheet := Book.Sheets[1];                  // Sheets is 1-based
    Pivot := Sheet.AddPivotTable('Data!$A$1:$D$800', 3, 6, 'RegionTotals');
    if Pivot = nil then
      raise Exception.Create('Bad source range or anchor');

    Region := Pivot.AddRowField('Region');    // nil if no such field
    if Region <> nil then
      Region.Subtotals := [xlpsDefault, xlpsAverage];  // -> t="default", t="avg"
    Pivot.AddColumnField('Quarter');
    Pivot.AddDataFieldByName('Revenue', xlpaSum);      // Revenue gets dataField="1"

    Book.SaveAs('orders-pivot.xlsx');
  finally
    Book.Free;
  end;
end;
Reading what Excel leaves out
The reader has the mirror-image problem. An Excel-made pivot field lists its subtotal entries in items, and loading them as ordinary members would give the field phantom items that point at no cache value. HotXLS skips any item whose t attribute is present and is not data, which covers subtotal, grand-total and blank entries. The subtotal functions arrive through the field's own flags and land in Subtotals, so code that walks Items sees real members only and every CacheItemIndex refers to a cache value
Missing attributes are the other half. In the schema, defaultSubtotal on CT_PivotField and containsString on CT_SharedItems both default to true, and Excel omits them when they hold that value. HotXLS reads an absent defaultSubtotal as true and adds xlpsDefault to Subtotals when the field carries no explicit subtotal flags, which is how Excel itself displays such a field. An absent containsString also reads as true, so a plain text cache field is classified as string data. Read either attribute as false and every pivot saved by Excel loses its automatic subtotals on load, while text fields turn into some other type. A writer that always spells out every attribute never touches this path; only files from another producer exercise it
A loaded Excel workbook is the right test input here, because it is the only kind of file that leaves those attributes out. The check below opens one and walks a row field:
var
  Book : TXLSXWorkbook;
  Pivot: TXLSPivotTable;
  Fld  : TXLSPivotField;
  I, J : Integer;
begin
  Book := TXLSXWorkbook.Create;
  try
    Book.Open('saved-by-excel.xlsx');
    Pivot := Book.Sheets[1].PivotTables.FindByName('PivotTable1');
    if Pivot = nil then
      Exit;
    for I := 0 to Pivot.FieldCount - 1 do
    begin
      Fld := Pivot.Fields[I];
      if Fld.Axis <> xlpfaRowField then
        Continue;
      // An Excel field with no subtotal attributes still reports the default
      if xlpsDefault in Fld.Subtotals then
        Writeln(Fld.Name, ': automatic subtotal');
      // Subtotal entries were skipped, so each item maps to a cache value
      for J := 0 to Fld.ItemCount - 1 do
        Assert(Fld.Items[J].CacheItemIndex >= 0);  // check suggested for your own tests
    end;
  finally
    Book.Free;
  end;
end;
Why numFmtId="General" is invalid on cache fields
numFmtId="General" is invalid because ST_NumFmtId is an unsigned integer, however natural it is to borrow the name users see in the Format Cells dialog. A parser that types attributes from the schema rejects the name outright, and that class of failure is exactly what turns into a repair dialog in Excel; the article on the OPC and markup rules behind the Excel repair prompt covers how those dialogs are triggered. HotXLS writes every cacheField with a numeric numFmtId taken from the cache field's NumberFormat, which is 0, the built-in General format, unless something set it
Pivot tables below row 65535 need 32-bit positions
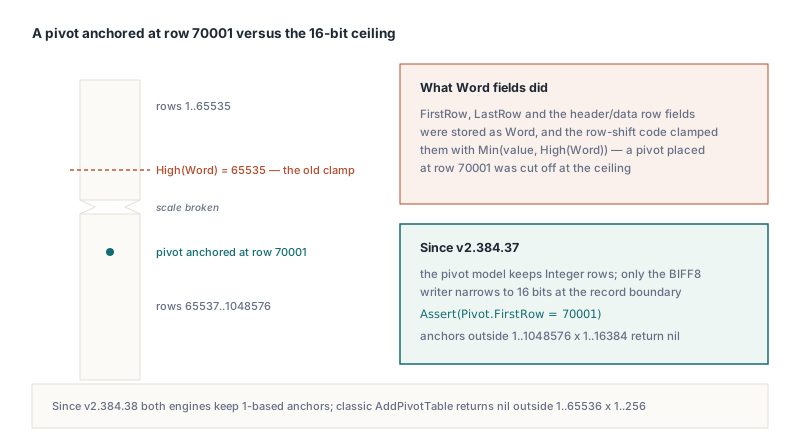
A pivot model shared by the XLS and XLSX engines is tempted to borrow its field widths from the BIFF8 SxView record, where 16 bits cover every row a classic sheet can hold. An XLSX sheet runs to 1,048,576 rows. Store FirstRow, LastRow, FirstHeaderRow, FirstDataRow and the column counterparts as Word, clamp them with Min(Value, High(Word)), and a pivot anchored at row 70001 gets cut off at 65535
On TXLSPivotTable those properties are Integer, and only the BIFF8 writer narrows them at the record boundary. TXLSXWorksheet.AddPivotTable returns nil for an anchor outside 1..1048576 by 1..16384, and AddPivotTableCopy returns nil when the copy's extent would run off the grid
var
  Book, Check: TXLSXWorkbook;
  Pivot      : TXLSPivotTable;
begin
  Book := TXLSXWorkbook.Create;
  try
    Book.Open('orders.xlsx');
    // Row 70001 is beyond the 16-bit range
    Pivot := Book.Sheets[1].AddPivotTable('Data!$A$1:$D$800', 70001, 1, 'LateTotals');
    if Pivot = nil then
      Exit;  // anchor outside the sheet or unresolvable source range
    Pivot.AddRowField('Region');
    Pivot.AddDataFieldByName('Revenue', xlpaSum);
    Book.SaveAs('late.xlsx');
  finally
    Book.Free;
  end;

  Check := TXLSXWorkbook.Create;
  try
    Check.Open('late.xlsx');
    Pivot := Check.Sheets[1].PivotTables.FindByName('LateTotals');
    // Assert is a check suggested for your own tests
    Assert((Pivot <> nil) and (Pivot.FirstRow = 70001));
  finally
    Check.Free;
  end;
end;
The classic XLS engine follows the same 1-based convention. The SxView and DConRef records store 0-based values, while the model, like the XLSX engine and Cells[Row, Col], keeps 1-based positions: the BIFF8 reader adds 1 and the writer subtracts 1 at the record boundary. The classic AddPivotTable returns nil for an anchor outside 1..65536 by 1..256, so anchor pivots at (1, 1) rather than (0, 0). The record layout itself is described in the BIFF8 SX records behind classic .xls pivot tables
Testing against the schema instead of your own reader
Every trap above survives a round trip when the forgiving side and the faulty side live in the same library. Three kinds of check catch them. A schema validation of the generated pivotTableN.xml and pivotCacheDefinitionN.xml parts catches invented tokens, empty items elements and named format ids. Files saved by Excel, fed through your reader, exercise the attributes that Excel omits at their defaults. Assertions that pin the exact token in the written XML, such as axis="axisRow", catch a writer drifting toward a spelling only your reader understands; asserting on the parsed axis cannot
Pivots built through the API, including the calculated fields, calculated items and percent-of-total layouts shown in building and refreshing XLSX pivot tables with calculated fields, come out with these rules applied and no extra code on your side. The work left for you is choosing which fields get subtotals and which count function you mean
The HotXLS Delphi spreadsheet component builds, reads and saves XLS and XLSX pivot tables from Delphi and C++Builder code, with no Excel installation or COM automation on the machine that runs it