PDFlibPas, the PDF Library for Delphi, imports TIFF images whose JPEG compression goes beyond 8-bit baseline: 12-bit extended sequential (SOF1), Huffman lossless (SOF3), arithmetic-coded (SOF9 and SOF10) and old-style TIFF 6.0 JPEG with table offsets. Because PDF DCTDecode cannot carry those processes, PDFlibPas decodes them in native Pascal and embeds the samples losslessly at 8 or 16 bits per component
The full set requires v3.724.0 or later, and it is aimed squarely at TIFFs from scanners, medical and scientific capture software, and archive systems frozen in the 1990s. Below is why these variants cannot be copied into the PDF as-is, how PDFlibPas lands them, and the Pascal traps found along the way
Why can't a 12-bit JPEG go straight into a PDF?
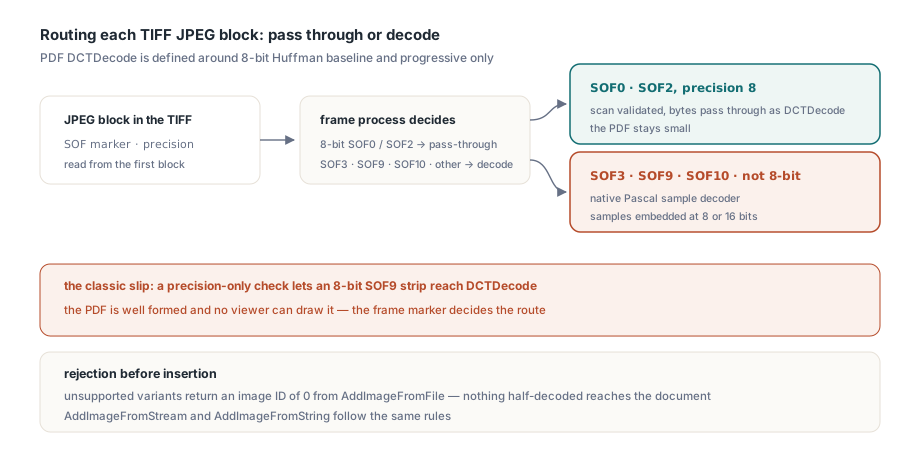
A 12-bit JPEG cannot be passed through because PDF has no filter that is required to decode it. ISO 32000-1 §7.4.8 defines DCTDecode around the JPEG baseline format, with the progressive extension added in PDF 1.3. Nothing in that clause covers 12-bit sample precision, the lossless process of ITU-T T.81 Annex H, or the arithmetic entropy coder of Annex D. A reader that meets an SOF1 12-bit frame or an SOF9 marker inside a DCTDecode stream is entitled to draw nothing, and most viewers do exactly that
For the 8-bit Huffman baseline and progressive strips that make up most JPEG-in-TIFF files, PDFlibPas still validates every scan and passes the compressed bytes through as DCTDecode, which keeps the PDF small. Everything else is decoded. PDFlibPas reads the frame marker and sample precision of the first JPEG block, and when it finds SOF3, SOF9, SOF10 or a precision other than 8, the page goes through the sample decoder instead of the pass-through path. Detecting arithmetic coding by its frame marker matters more than it sounds: a check that looks only at sample precision lets a classic TIFF slip an 8-bit SOF9 strip into the DCTDecode path and produce a PDF that readers cannot display
What PDFlibPas writes into the PDF instead
PDFlibPas turns decoded JPEG blocks into an ordinary image XObject with BitsPerComponent 8 or 16. The samples are stored uncompressed by default; call CompressImages(1) before adding the image and PDFlibPas writes them with FlateDecode. ISO 32000-1 §8.9.5.1 permits 16 bits per component from PDF 1.5, so PDFlibPas raises the document version to at least 1.5 whenever an image with 16-bit samples is added. That includes multi-strip and tiled images, whose root object is a Form XObject with no BitsPerComponent of its own to inspect
The mapping is fixed per JPEG process:
- 12-bit Huffman JPEG (sequential SOF1, progressive SOF2) is dequantised, inverse transformed and widened to 16-bit samples
- Arithmetic-coded JPEG (sequential SOF9, progressive SOF10) becomes 8-bit samples at 8-bit precision and 16-bit samples at 12-bit precision
- Huffman lossless JPEG (SOF3) becomes 8-bit or 16-bit samples, matching its declared precision exactly
The widening from 12 to 16 bits uses bit replication, (V shl 4) or (V shr 8), so 4095 maps to 65535 and white stays white instead of topping out at 65520. PDFlibPas never drops these images to 8 bits behind your back. When the library rasterises such a page for its own display surface it uses the high byte of each sample, but the embedded PDF image keeps all sixteen
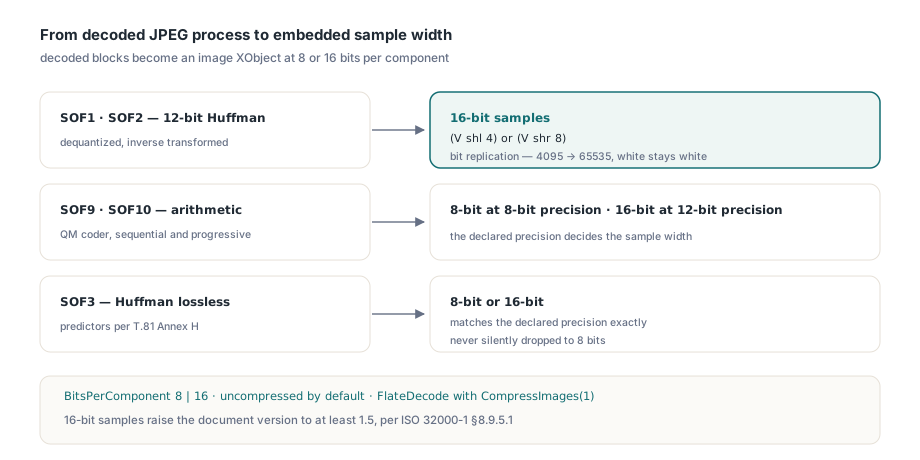
The price is file size: even with CompressImages(1), Flate-compressed 16-bit samples are larger than the DCT data they came from, and without it they are larger still. For diagnostic and archival workflows that trade is usually right. If size matters more for a given job, the guide to reducing PDF file size in Delphi shows where the bytes actually go
Importing these TIFFs with TPDFlib
The calling code does not change at all. TPDFlib.AddImageFromFile(Const FileName: WideString; Options: Integer): Integer takes the 1-based TIFF page number in Options and returns an image ID, or 0 when the page cannot be imported. Unsupported JPEG variants are rejected before the image is inserted, so a 0 means nothing half-decoded reached the document
uses
  PDFlibrary;

function TiffToPdf(const TiffName, PdfName: WideString): Boolean;
var
  Lib: TPDFlib;
  Page, PageCount, ImageID: Integer;
  DPI, W, H: Double;
begin
  Result := False;
  Lib := TPDFlib.Create;
  try
    Lib.SetMeasurementUnits(0);   // default user space, 1/72 inch
    Lib.SetOrigin(1);             // top-left origin for DrawImage
    Lib.CompressImages(1);        // Flate for decoded samples
    PageCount := Lib.GetImagePageCount(TiffName);
    if PageCount = 0 then
      Exit;
    for Page := 1 to PageCount do
    begin
      ImageID := Lib.AddImageFromFile(TiffName, Page);  // Options = TIFF page
      if ImageID = 0 then
        Exit;                     // unsupported or damaged image data
      Lib.SelectImage(ImageID);
      case Lib.ImageResolutionUnits of
        2: DPI := Lib.ImageHorizontalResolution;          // dots per inch
        3: DPI := Lib.ImageHorizontalResolution * 2.54;   // dots per cm
      else
        DPI := 0;
      end;
      if DPI <= 0 then
        DPI := 300;
      W := Lib.ImageWidth * 72 / DPI;
      H := Lib.ImageHeight * 72 / DPI;
      if Page > 1 then
        Lib.NewPage;
      Lib.SetPageDimensions(W, H);
      Lib.DrawImage(0, 0, W, H);
    end;
    Result := Lib.SaveToFile(PdfName) = 1;
  finally
    Lib.Free;
  end;
end;
No per-format branching is needed, and AddImageFromStream and AddImageFromString follow the same rules for TIFF data held in memory
Old-style JPEG: tables at offsets, strips without headers
Since v3.713.0, PDFlibPas imports old-style JPEG TIFFs (Compression = 6) whose tables come from the JPEGQTables, JPEGDCTables and JPEGACTables offset tags or from a tables-only JPEGInterchangeFormat stream. TIFF 6.0 Section 22 defined that layout, and TIFF Technical Note 2 later replaced it with Compression = 7 and a shared JPEGTables tag, but scanners kept writing the old form for years
The container side, BigTIFF and tiled layouts, is covered in the write-up on hardening the TIFF decoder; here the focus is the JPEG payload. Each table-offset tag points at a raw 64-byte quantisation table, or at a Huffman table of 16 counts followed by its values, one entry per component. PDFlibPas turns those into DQT and DHT segments in a synthesised JPEGTables stream. Each strip of bare entropy-coded data then gets a header of its own: SOI, a frame marker carrying that strip's row count, DRI when JPEGRestartInterval is set, SOS, the entropy data and EOI. The strips cannot be glued into one scan, because old-style JPEG restarts DC prediction at every strip boundary
Two details are easy to get wrong. The three components of a YCbCr image often point their table offsets at the same bytes, so PDFlibPas deduplicates tables by content before it assigns table numbers. If more than two Huffman tables of one class remain, the synthesised frame uses SOF1 instead of SOF0, since a baseline frame may reference only two DC and two AC tables. When JPEGInterchangeFormat instead points at a complete JPEG stream that contains scans, PDFlibPas treats that stream as the whole image and imports it as a single new-style strip. Lossless, tiled and separate-plane old-style JPEG are refused with an explicit error rather than guessed at, so convert those to new-style JPEG upstream
Why does a CMYK JPEG inside a TIFF come out inverted?
A CMYK JPEG inside a TIFF comes out inverted when the importer applies the Adobe APP14 convention that belongs to standalone JPEG files. Photoshop writes inverted CMYK into standalone JPEGs, so PDF producers traditionally add /Decode [1 0 1 0 1 0 1 0] to compensate. TIFF PhotometricInterpretation 5 defines samples as ink amounts where 0 means no ink, and mainstream TIFF readers take the decoded JPEG samples at face value without looking at APP14
PDFlibPas embeds JPEG-compressed CMYK TIFF strips without the inverted Decode array, whether or not an APP14 marker is present. The APP14 transform flag still decides whether YCCK is converted to CMYK, and DCTDecode handles that step by itself. Standalone four-component JPEG files keep the inverted Adobe convention, so identical JPEG bytes are treated differently depending on the container, as the two formats demand
Why does lossless JPEG decoding break on a Pascal shift?
Lossless JPEG decoding breaks in Pascal because predictors 5 and 6 need an arithmetic right shift and Pascal's shr is a logical one. SOF3 predicts each sample from its left (Ra), upper (Rb) and upper-left (Rc) neighbours and codes only the difference. Of the seven predictors in T.81 Table H.1, predictor 5 is Ra + ((Rb - Rc) >> 1) and predictor 6 is Rb + ((Ra - Rc) >> 1), and the bracketed difference goes negative whenever the upper-left neighbour is the brighter one. Feed a negative Integer to shr and the sign bit becomes a magnitude bit, so the image dissolves into noise
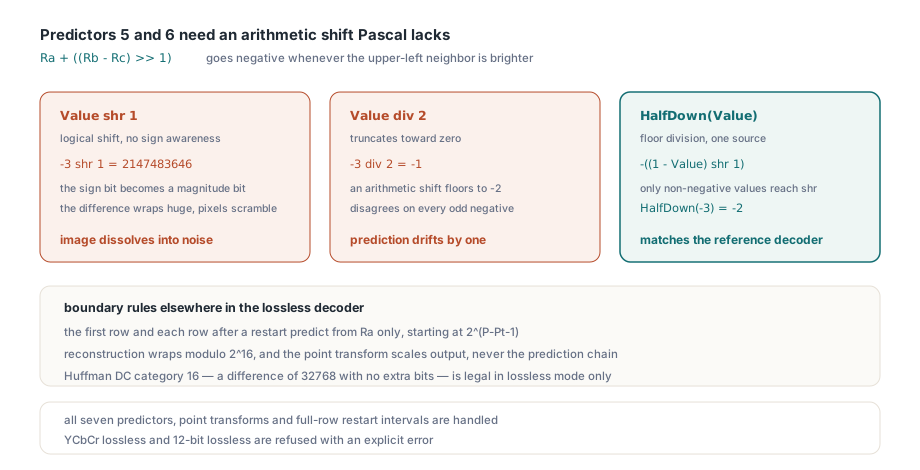
Swapping the shift for div 2 does not fix it either. div truncates towards zero while an arithmetic shift rounds towards negative infinity, and the two disagree on every odd negative value. Free Pascal has SarLongint in its System unit; Delphi has no equivalent, so PDFlibPas uses a helper that compiles identically on both:
// Arithmetic shift right by one: floor(Value / 2)
// shr is a logical shift, and div 2 truncates towards zero
function HalfDown(Value: Integer): Integer;
begin
  if Value >= 0 then
    Result := Value shr 1
  else
    Result := -((1 - Value) shr 1);
end;

// Value = -3:  -3 shr 1 = 2147483646,  -3 div 2 = -1,  HalfDown(-3) = -2
For the type-width side of the same class of problem, see Longint and pointer pitfalls on Delphi Linux64
The rest of the lossless decoder has boundary rules of its own. The first row, and the first row after each restart marker, predicts from the left neighbour only and starts at 2^(P−Pt−1) for precision P and point transform Pt; every later row starts from the sample above. Reconstruction wraps modulo 2^16, and the point transform scales only the output, never the prediction chain. Huffman DC category 16, a difference of 32768 with no extra bits, is legal only in lossless mode, so the table parser has to accept it before it knows which process the frame will declare
PDFlibPas supports all seven predictors, point transforms and restart intervals that cover whole rows. The JPEG precision must equal BitsPerSample and be 8 or 16, and every component must be sampled 1x1. YCbCr lossless data and 12-bit lossless JPEG are refused with an explicit error
12-bit DCT and arithmetic coding in native Pascal
The 12-bit and arithmetic decoders in PDFlibPas share one inverse DCT and differ only in entropy decoding. In 12-bit Huffman JPEG, DC categories reach 15 and AC categories 14, quantisation tables may carry 16-bit entries, and DC prediction resets at every scan and every restart. Coefficients stay in zigzag order until dequantisation, which must use the quantisation value at the same zigzag index, and only then move to natural order for the separable two-pass IDCT. Decoded samples land within ±1 of an independent floating-point reference decoder
Arithmetic coding replaces Huffman with the QM coder of T.81 Annex D: a 114-entry probability state table, a 64-bin DC statistics area and a 256-bin AC area, steered by conditioning parameters from the DAC segment (defaults L = 0, U = 1, Kx = 5). Statistics, DC context and prediction reset at every restart interval and at the start of every scan. That is why PDFlibPas keeps DAC segments when it normalises shared JPEGTables for arithmetic images; drop them and every strip decodes with the wrong statistics model
v3.723.0 added subsampled components and YCbCr-to-RGB conversion with the JFIF equations to these decoded paths, and v3.724.0 added progressive scans for both 12-bit Huffman (SOF2) and arithmetic (SOF10) data. Subsampled chroma is replicated to full resolution rather than smoothed, which is what a reference decoder produces with chroma smoothing turned off. Hierarchical JPEG and arithmetic-coded lossless JPEG (SOF11) are refused with an explicit error
Testing binary JPEG fixtures in Delphi
Hand-built JPEG fixtures in Delphi unit tests can fail in a way that looks exactly like a decoder bug. A string constant built from #$xx characters that runs past 255 characters is typed as UnicodeString, and assigning it to an AnsiString converts it through the active code page. Bytes $80 to $9F, which are routine in entropy-coded data, get rewritten on the way in. Building marker headers at runtime has the same trap: in Delphi, AnsiChar + AnsiChar yields a UnicodeString, so append single bytes to an AnsiString or write them with SetLength and indexed assignment. For fixtures, store hex text and decode it at runtime:
uses
  SysUtils, PDFlibrary;

function HexToBytes(const Hex: AnsiString): AnsiString;
var
  I: Integer;
begin
  SetLength(Result, Length(Hex) div 2);
  for I := 1 to Length(Result) do
    Result[I] := AnsiChar(StrToInt('$' + string(Copy(Hex, I * 2 - 1, 2))));
end;

// The fixture stays plain ASCII, so no code page can touch it
ImageID := Lib.AddImageFromString(HexToBytes(TiffHex), 1);
When generating test images, note that jpegtran -arithmetic writes sequential SOF9; SOF10 needs -progressive as well. And a non-zero image ID only proves the import was accepted. Render the page and compare pixels, because a pass-through mistake produces a well-formed PDF that no viewer can draw
Bringing legacy scan archives into PDF
These JPEG variants tend to surface all at once during an archive migration. PDFlibPas reads 12-bit, lossless, arithmetic and old-style JPEG TIFFs through the same AddImageFromFile call as everything else, keeps full precision in the PDF, and refuses the rare processes outside that set with an explicit error. For licensing, the full feature list and trial downloads, see the PDFlibPas PDF Library for Delphi product page